TL;DR
A developer reportedly increased Qwen3.8-27B text generation speeds on an RTX 3090 from 82 to 382 tokens per second through inference engine optimizations.
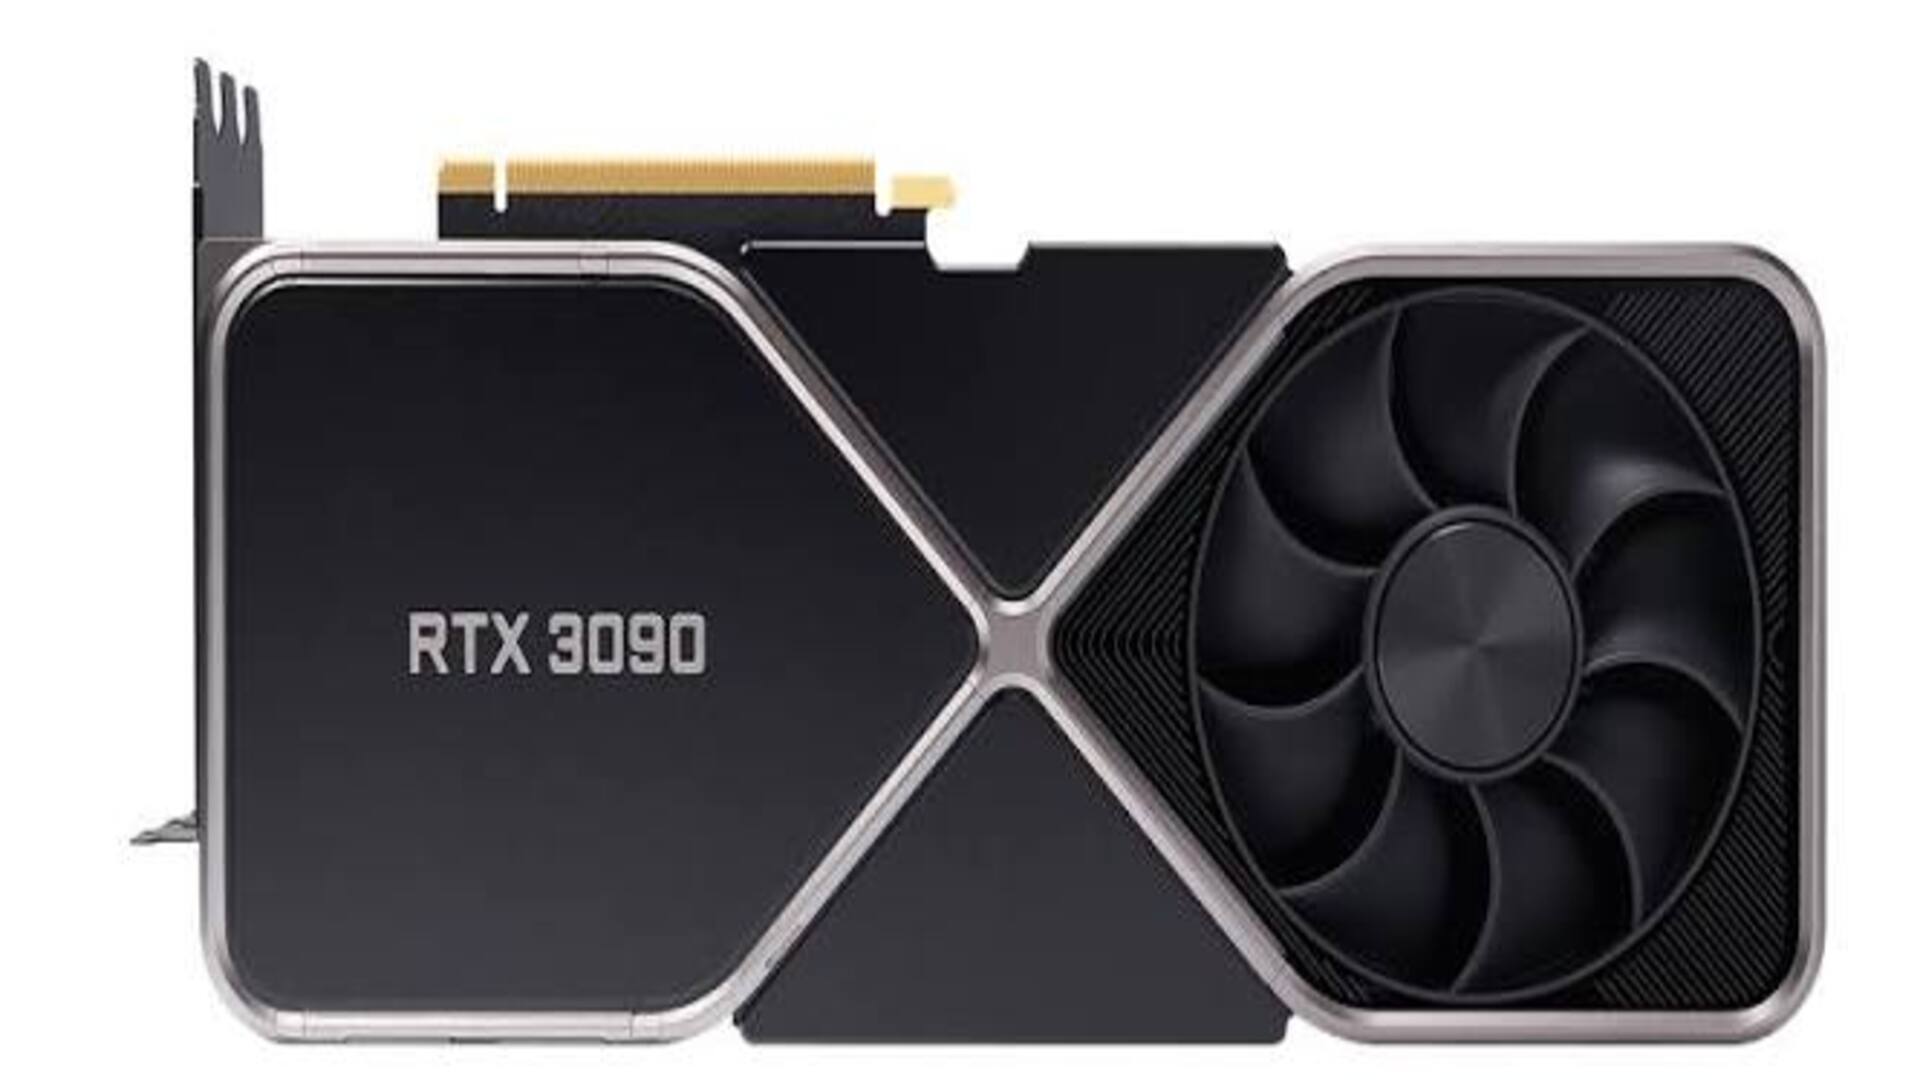
A developer has reportedly increased the text generation speed of the Qwen3.8-27B language model on a single Nvidia GeForce RTX 3090 by 4.6 times. Reports say speeds rose from 82 tokens per second to 382 tokens per second using the 24GB VRAM card. These improvements came from optimizing the inference engine rather than changing the GPU hardware.
The developer used speculative decoding and added a lookup drafter to propose multiple tokens at once for the main model to validate. This approach expanded the context window to nearly 139,000 tokens through a compact working memory format. For standard chat interactions, the system reportedly maintains 133 tokens per second. However, drawbacks include initial document reads taking double the time while extended verification requires extra memory.
Earlier coverage

Quick read
GALAX says its GeForce RTX 5090 Hall of Fame Edition, which features embedded Swarovski crystals, is scheduled for launch on October 22.

Quick read
Samsung is reportedly working with TSMC to produce base dies for NVIDIA's NVHBM memory standard while using its own processes for the memory chips.
Quick read
Two pallets of Zotac RTX 5090 GPUs worth approximately $470,000 disappeared from Guarulhos International Airport in Brazil, according to reports.
Quick read
Reports indicate Samsung will use TSMC's 3nm process for Nvidia's next-generation custom high-bandwidth memory base dies.